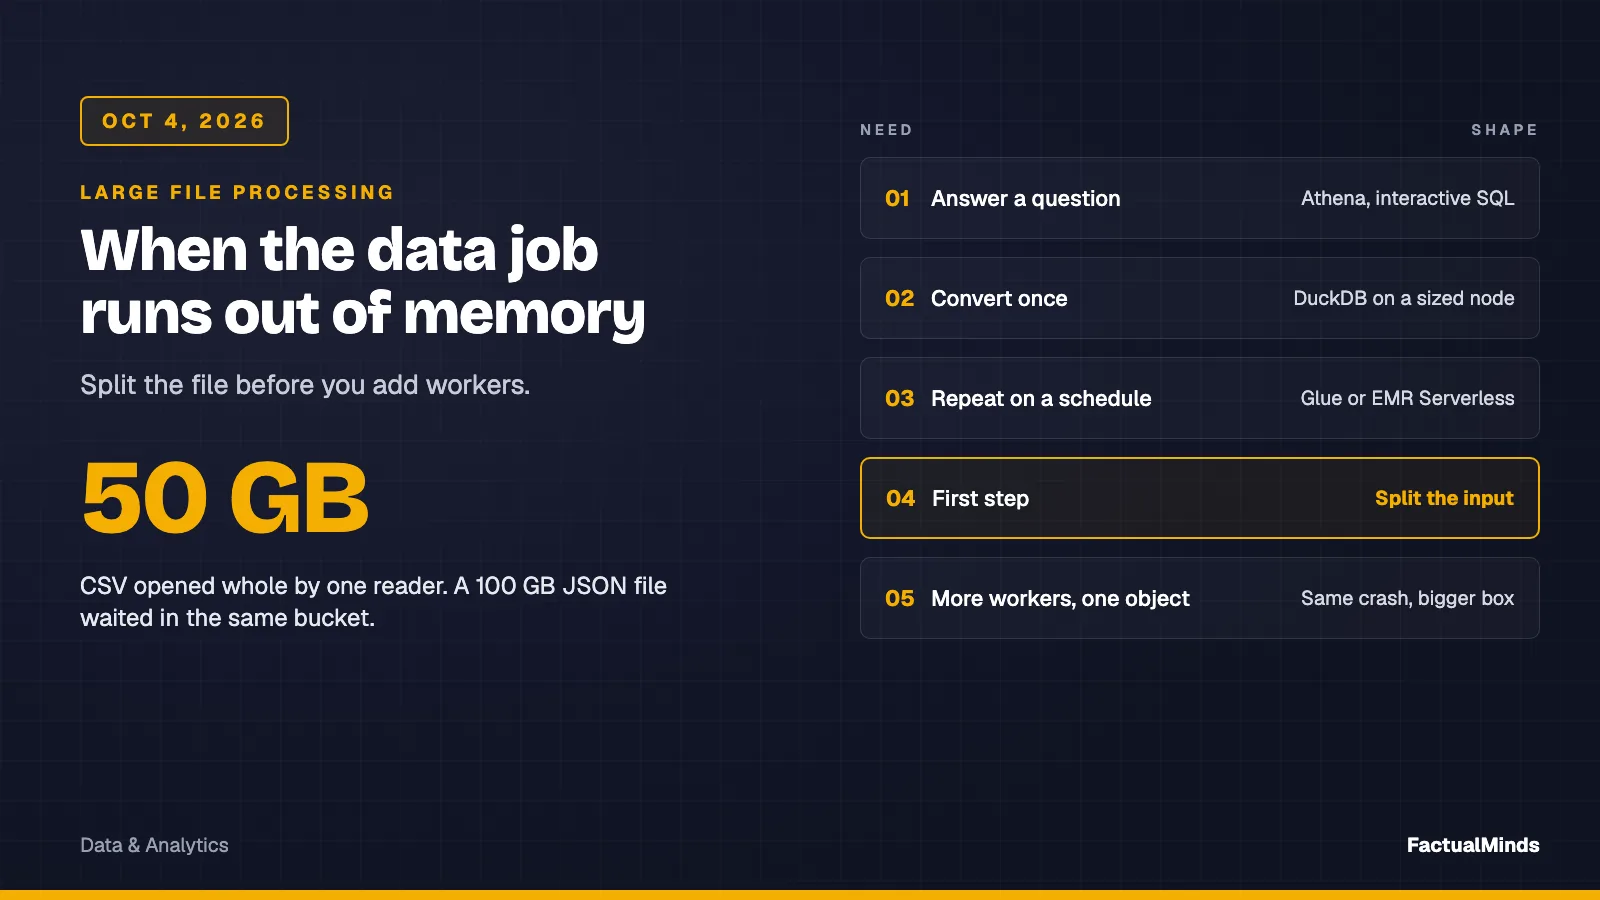
When the Data Job Runs Out of Memory
A 50 GB or 100 GB CSV loaded whole dies in a small worker. Split the job into interactive SQL, a one-shot conversion, or a repeating pipeline. Adding workers does not split a file nobody partitioned.
2 min read
Blog category
Data engineering guides on building AWS data lakes, streaming pipelines with Kinesis, serverless ETL with Glue and Athena, and BI dashboards with QuickSight. Patterns for moving from ad-hoc SQL to production-grade analytics infrastructure.
A 50 GB or 100 GB CSV loaded whole dies in a small worker. Split the job into interactive SQL, a one-shot conversion, or a repeating pipeline. Adding workers does not split a file nobody partitioned.
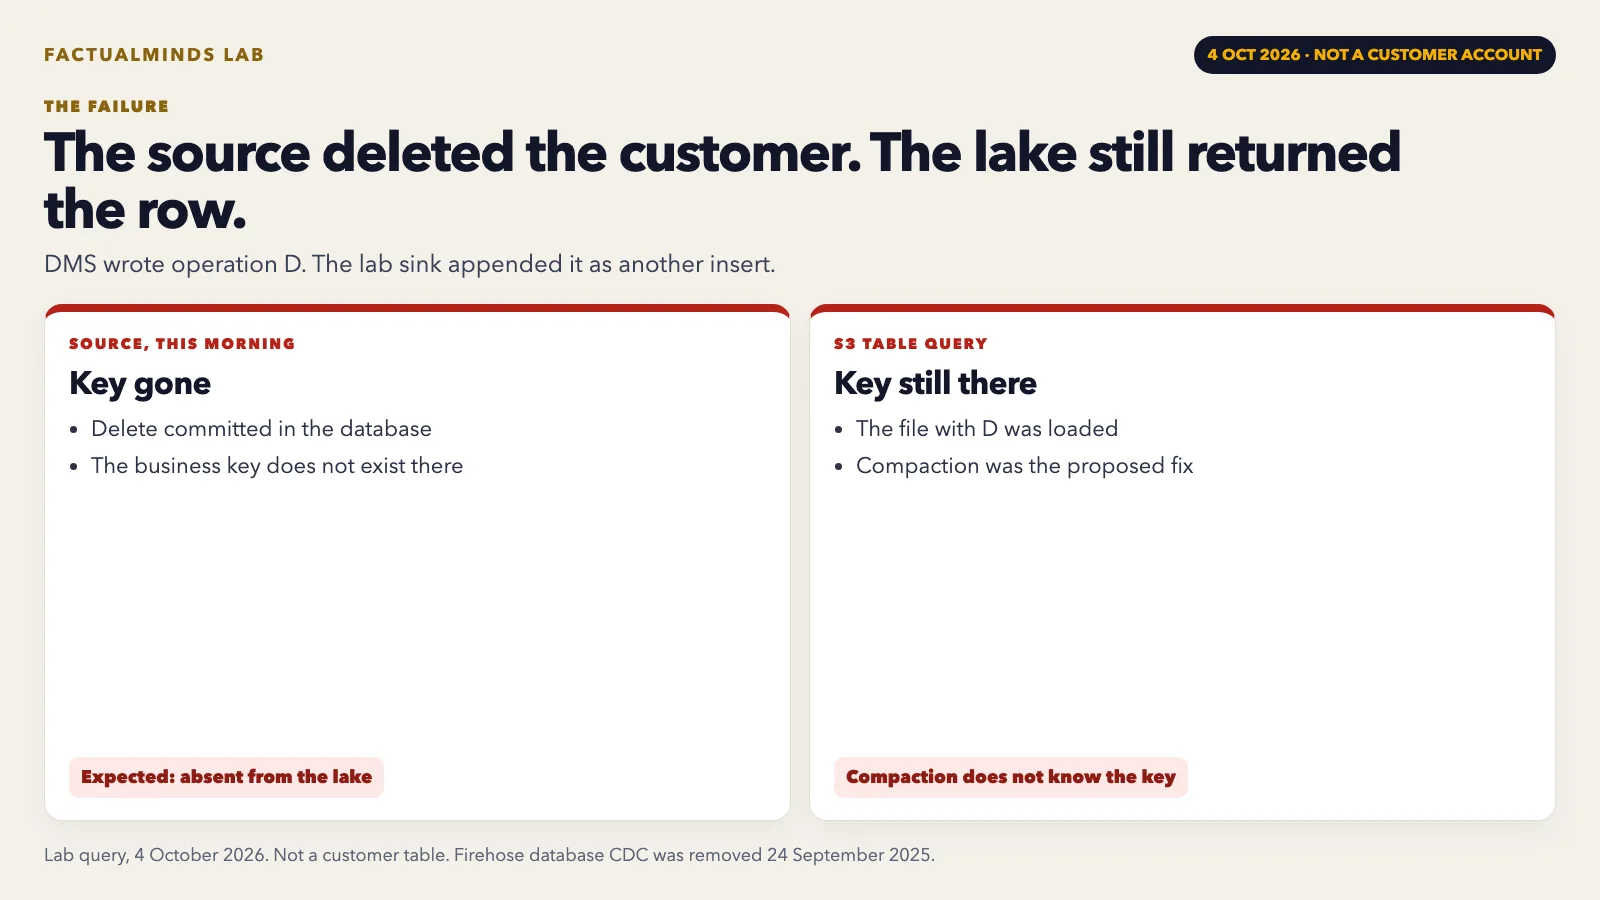
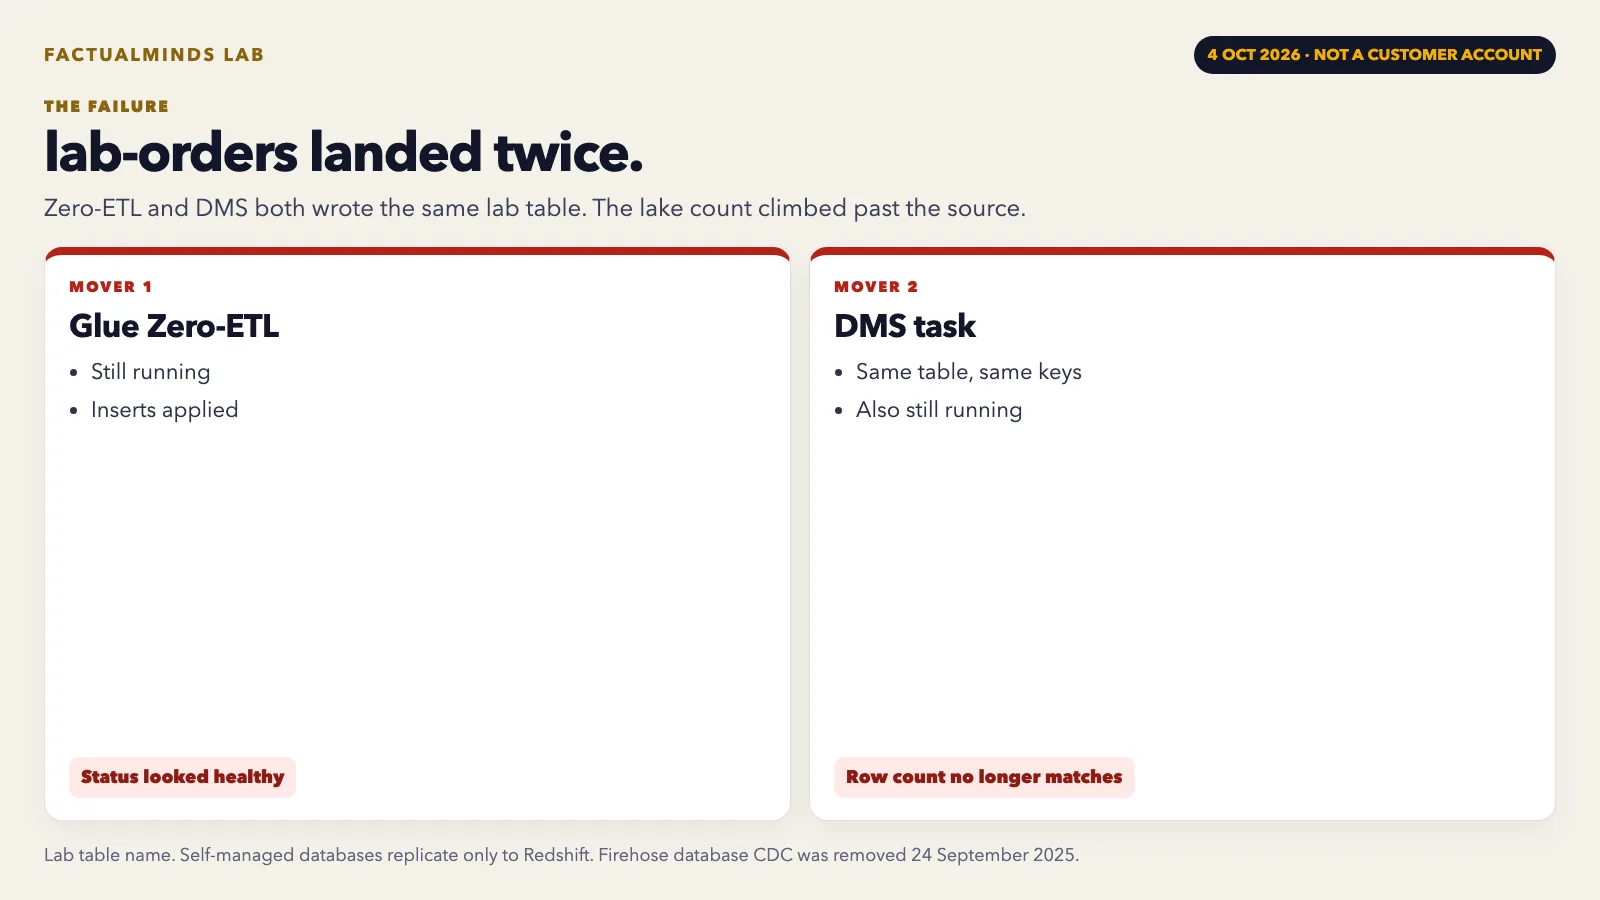
A lab table landed twice: Zero-ETL and DMS on the same rows. Self-managed databases replicate only to Redshift. Firehose Direct PUT into Iceberg is capped at 5 MiB/s in three regions, and database CDC was removed on 24 September 2025.
 Palaniappan P
For a retailer DW exit (~42 TB logical, 18 nightly Glue jobs), Aurora→Redshift zero-ETL retired 11 jobs and cut dashboard freshness from 6h to ~15 min. Concurrency scaling on zero-ETL (March 2026) absorbed Monday open spikes.
Palaniappan POn a multi-domain retailer (~4,200 Glue tables, 11 AWS accounts), publishing a stewardship RACI plus SageMaker Catalog subscriptions cut mean time-to-data-access from 19 days to 4 days, without replacing Lake Formation enforcement.
Palaniappan PFor a specialty retailer (~380 stores, 2.4M loyalty members), S3 Tables Iceberg silver plus Kinesis cart events cut dashboard refresh from 26 hours to 22 minutes, and conversion reporting error dropped from 11% to 2%.
Palaniappan PCopying curated Parquet into every consumer account is how data platforms drown in storage cost and permission sprawl. On Feb 11, 2026 AWS shipped Lake Formation cross-account version 5, which adds wildcard RAM shares for hundreds of thousands of tables. A composite 12-account platform cut duplicate curated copies from 3 to 0 and dropped cross-account access tickets from ~11/month to ~3 by standardizing LF-Tags + resource links.
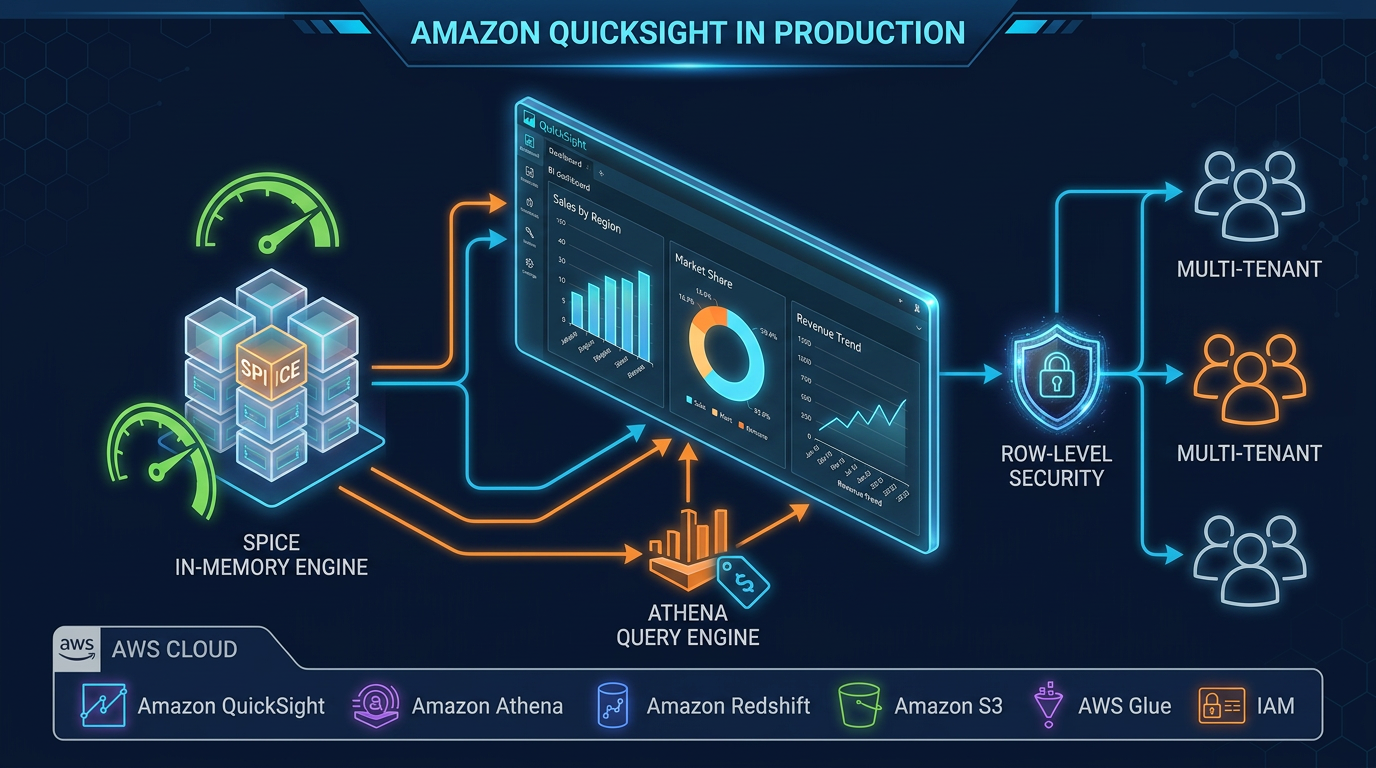
Palaniappan PAmazon QuickSight can replace expensive BI tools or become a costly mistake, depending on how you use it. This production guide covers SPICE, multi-tenancy, cost control, and the cases where QuickSight is the wrong choice.
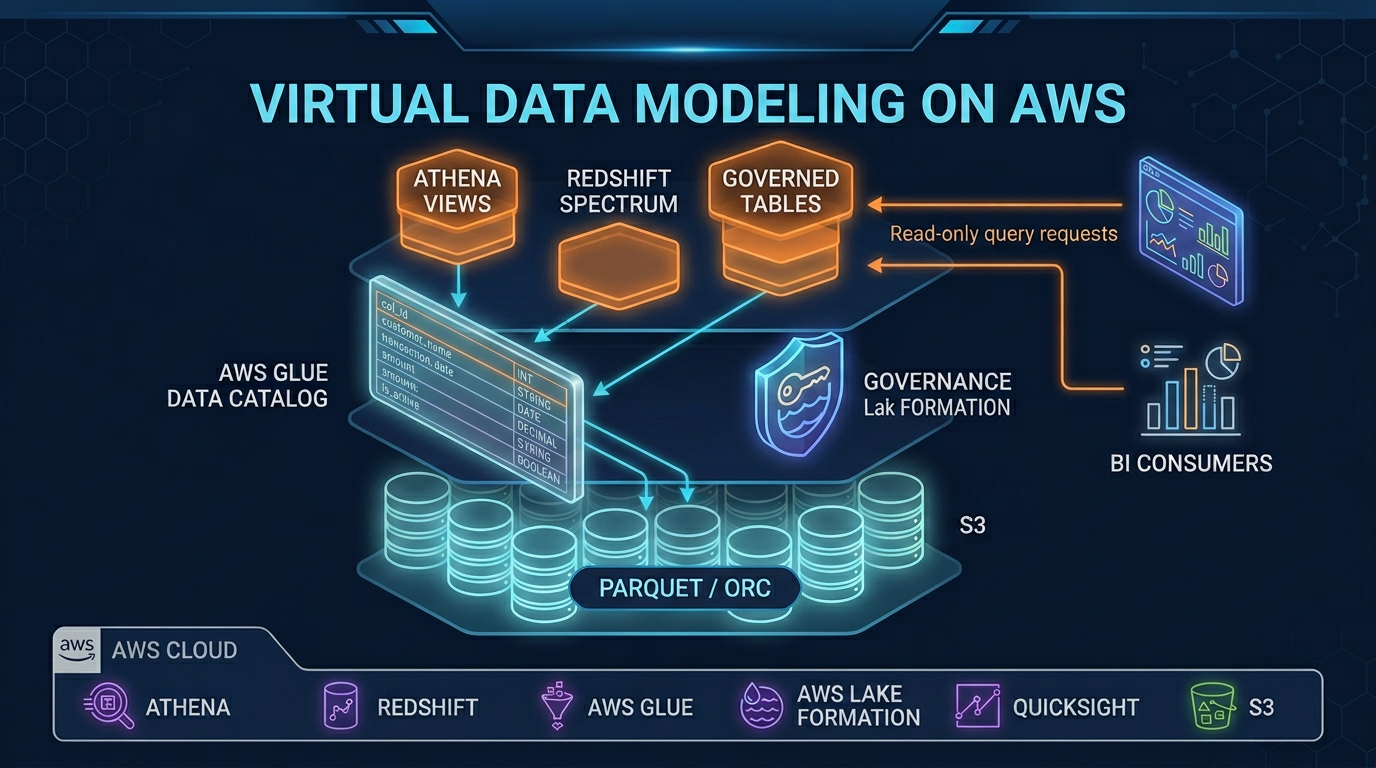
Palaniappan PVirtual data modeling on AWS: Athena/Redshift semantic views without copies. As of July 2026, when VDM works and when it burns Athena dollars.
Palaniappan PWe use cookies and similar technologies to analyze site traffic, personalize content, and provide social media features. By clicking “Accept,” you consent to our use of cookies. You can adjust your preferences at any time.