How to Build a RAG Pipeline with Amazon Bedrock Knowledge Bases
Quick summary: Amazon Bedrock Knowledge Bases automate the RAG (Retrieval-Augmented Generation) pipeline — semantic search, chunking, embedding, and context injection into Claude or other foundation models. This guide covers setup, data ingestion, cost optimization, and production patterns.
Key Takeaways
- Amazon Bedrock Knowledge Bases automate the RAG (Retrieval-Augmented Generation) pipeline — semantic search, chunking, embedding, and context injection into Claude or other foundation models
- AWS lifecycle notice (June 30, 2026) — Amazon Bedrock Agents Classic is now Bedrock Agents Classic, in maintenance for new customers after July 30, 2026
- Net-new agent builds should use Bedrock AgentCore
- Amazon Bedrock Knowledge Bases simplify building Retrieval-Augmented Generation (RAG) applications
- Instead of orchestrating chunking, embedding, vector search, and context injection manually, Bedrock handles the pipeline end-to-end
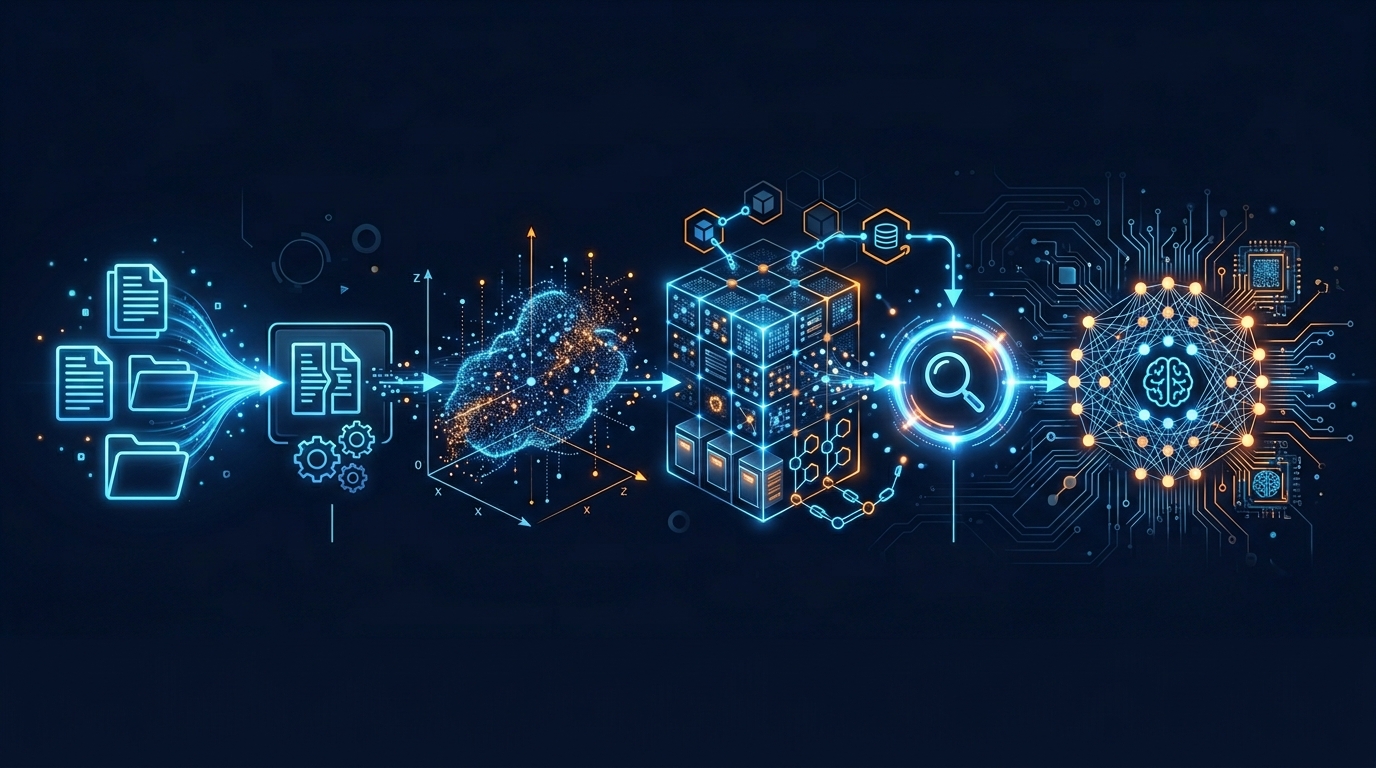
Table of Contents
AWS lifecycle notice (June 30, 2026) — Amazon Bedrock Agents Classic is now Bedrock Agents Classic, in maintenance for new customers after July 30, 2026. Net-new agent builds should use Bedrock AgentCore. Full matrix: lifecycle roundup.
Amazon Bedrock Knowledge Bases simplify building Retrieval-Augmented Generation (RAG) applications. Instead of orchestrating chunking, embedding, vector search, and context injection manually, Bedrock handles the pipeline end-to-end. Upload documents → Bedrock chunks and embeds them → retrieval happens automatically when you invoke Claude or other foundation models with the knowledge base.
This guide covers the full setup: creating and configuring a knowledge base, ingesting documents, querying it from your application, and optimizing for production cost and latency.
Building GenAI on AWS? FactualMinds helps teams architect and deploy Bedrock applications at scale. See our AWS Bedrock consulting services or talk to our team.
Step 1: Create an Amazon Bedrock Knowledge Base
Start in the AWS Console:
- Navigate to Amazon Bedrock → Knowledge Base
- Click Create Knowledge Base
- Name:
my-company-kb(lowercase, no spaces) - Description: Optional but recommended for tracking
- Select an embedding model: Choose from:
- Titan Embeddings (default, $0.08 per 1M tokens, fully managed)
- Custom embeddings (requires external OpenSearch or vector database)
For most use cases, Titan Embeddings is sufficient. It understands semantic relationships across business documents, code, and technical content.
- Click Next
Step 2: Configure Data Source and Vector Store
Bedrock needs two things: a data source (where documents live) and a vector store (where embeddings are stored).
Step 2A: Data Source
Choose where your documents are stored:
S3 bucket (recommended for bulk ingestion)
- Create an S3 bucket or select an existing one:
s3://my-company-docs/ - Bedrock will scan for supported files: PDF, DOCX, TXT, MD, HTML
- Set an S3 prefix if documents are in a subdirectory:
bedrock-documents/
- Create an S3 bucket or select an existing one:
Web crawler (less common, for public websites)
- Useful for ingesting documentation sites, but adds complexity
For this guide, use S3 bucket.
Step 2B: Vector Store
Choose a vector store when creating the knowledge base:
- Amazon S3 Vectors (recommended for new RAG workloads in 2026) — S3-native vector storage at lower cost for large corpora; see S3 Vectors guide.
- OpenSearch Serverless — Bedrock can auto-create a collection named
bedrock-kb-{timestamp}; use when you need hybrid BM25 + vector search or sub-50ms retrieval. - Aurora PostgreSQL (pgvector) — when you already operate Aurora and want SQL-adjacent ops.
For OpenSearch Serverless, you are charged for OCU-hours plus storage (historically ~$108/month minimum at small scale). S3 Vectors targets storage-economics workloads above ~10M vectors. Pick based on latency and hybrid-search requirements — not defaulting to OpenSearch without a reason.
Click Create and Ingest to proceed.
Step 3: Ingest Documents into the Knowledge Base
Once the knowledge base is created, upload documents:
In the Knowledge Base page, select your KB and go to Documents
Upload documents:
- Drag-and-drop files or click to browse
- Supported formats: PDF, DOCX, TXT, MD, HTML, JSON, CSV (as semi-structured)
- Max file size: 50MB per document
Chunking strategy (default is fine for most cases):
- Chunk size: 2,048 tokens (≈ 1,500 words)
- Overlap: 512 tokens (improves semantic coherence at chunk boundaries)
- These settings are NOT customizable in the console; to use custom chunking, use the API
Metadata filtering (optional):
- Add document metadata like
department: engineering,year: 2026 - Metadata can be used in retrieval queries to filter results
- Add document metadata like
Click Upload and ingest
Expected duration: Ingestion takes ~1 minute per 100MB of documents. A 1GB knowledge base takes ~10 minutes.
Step 4: Query the Knowledge Base from Your Application
Bedrock knowledge bases integrate with the Agents API and regular model invocation. Here’s how to retrieve documents and pass them to Claude:
Using the Agents API (recommended for production):
import boto3
import json

bedrock_agent_client = boto3.client('bedrock-agent-runtime', region_name='us-east-1')
kb_id = 'your-knowledge-base-id'

response = bedrock_agent_client.retrieve_and_generate(
    input={'text': 'How does our cost optimization framework work?'},
    retrievalConfiguration={
        'vectorSearchConfiguration': {
            'numberOfResults': 5,
            'overrideSearchType': 'HYBRID'  # Combines vector + keyword search
        }
    },
    sessionConfiguration={
        'kmsKeyArn': 'arn:aws:kms:us-east-1:123456789012:key/12345678-1234-1234-1234-123456789012'  # Optional encryption
    },
    knowledgeBaseId=kb_id,
    modelId='anthropic.claude-sonnet-4-6'  # Pin after benchmark — Sonnet 5 (2026-06-30) for agentic lanes; verify in console
)

print(response['output']['text'])
This does three things:
- Retrieves the top 5 most semantically similar documents from the KB
- Generates a response using Claude Sonnet 5.5 (or Sonnet 5 as the prior pin) with those documents as context
- Returns a single text response
Using the Bedrock Runtime API (for custom control):
If you need more control over the prompt or want to inject context into your own LLM calls:
bedrock_runtime_client = boto3.client('bedrock-runtime', region_name='us-east-1')
bedrock_agent_client = boto3.client('bedrock-agent-runtime', region_name='us-east-1')

# Step 1: Retrieve documents from KB
retrieval_results = bedrock_agent_client.retrieve(
    knowledgeBaseId=kb_id,
    retrievalConfiguration={
        'vectorSearchConfiguration': {
            'numberOfResults': 5,
            'overrideSearchType': 'HYBRID'
        }
    },
    text='How does our cost optimization framework work?'
)

# Step 2: Format documents as context
context = '\n\n'.join([
    f"Source: {item['metadata'].get('source', 'Unknown')}\n{item['content']['text']}"
    for item in retrieval_results['retrievalResults']
])

# Step 3: Invoke Claude with context
response = bedrock_runtime_client.invoke_model(
    modelId='anthropic.claude-sonnet-4-6',  # Pin after benchmark — Sonnet 5 (2026-06-30) for agentic lanes; verify in console
    body=json.dumps({
        'anthropic_version': 'bedrock-2023-06-01',
        'max_tokens': 2048,
        'messages': [
            {
                'role': 'user',
                'content': f"""You are a helpful assistant with access to company documentation.

Here is the relevant documentation:

<company_docs>
{context}
</company_docs>

User question: How does our cost optimization framework work?"""
            }
        ]
    })
)

print(json.loads(response['body'].read())['content'][0]['text'])
The second approach gives you full control over the prompt but requires you to handle chunking and deduplication yourself.
Step 5: Optimize Cost and Performance
Chunk size tuning:
- Small chunks (500 tokens): Fast retrieval, better precision on specific Q&A (e.g., “What’s the pricing for service X?”), but requires more API calls if you retrieve multiple chunks
- Large chunks (4,000+ tokens): Slower retrieval, better for narrative documents (e.g., whitepapers, architectural guides), fewer chunks needed
- Default (2,048 tokens) is a good balance. Use the API to customize:
bedrock_agent_client.create_knowledge_base_data_source(
    knowledgeBaseId=kb_id,
    dataSourceConfiguration={
        'type': 'S3',
        's3BucketConfiguration': {
            'bucketArn': 'arn:aws:s3:::my-company-docs',
            'inclusionPrefixes': ['bedrock/'],
            'parsingConfiguration': {
                'parsingStrategy': 'BEDROCK_NATIVE',
                'bedrockNativeConfiguration': {
                    'parseDocumentPayloadFlag': True,
                    'parseHtmlTagConfiguration': {
                        'htmlTagsToExclude': ['script', 'style']
                    }
                }
            }
        }
    }
)
Filtering by metadata:
Use metadata to reduce the number of results returned (faster, cheaper):
response = bedrock_agent_client.retrieve_and_generate(
    input={'text': 'How does our cost optimization framework work?'},
    retrievalConfiguration={
        'vectorSearchConfiguration': {
            'numberOfResults': 5,
            'filter': {
                'equals': [
                    {'key': 'department', 'value': 'engineering'},
                    {'key': 'year', 'value': '2026'}
                ]
            }
        }
    },
    knowledgeBaseId=kb_id,
    modelId='anthropic.claude-sonnet-4-6'  # Pin after benchmark — Sonnet 5 (2026-06-30) for agentic lanes; verify in console
)
Monitoring and cost:
- Knowledge Base provisioning: $0.15/hour = $108/month (non-negotiable minimum)
- Retrieval (GET): $0.15 per 1,000 calls
- Ingestion (PUT): $0.15 per 1,000 uploads
- Embeddings: $0.08 per 1M tokens (only if using Bedrock embeddings)
At 1,000 queries/day: $108 + ~$45/month in retrieval costs. At 10,000+ queries/day, consider OpenSearch Serverless with Titan Embeddings for potentially lower costs.
Step 6: Production-Ready Patterns
Hybrid Search (Vector + Keyword):
The HYBRID search type combines semantic similarity (vectors) with keyword matching, improving precision:
'overrideSearchType': 'HYBRID' # Recommended for productionReranking with Claude:
For high-stakes applications (e.g., customer support), retrieve more documents (e.g., 20) and have Claude rerank them:
# Retrieve 20 results, then ask Claude to pick the best 3
response = bedrock_agent_client.retrieve_and_generate(
    input={'text': 'How does our cost optimization framework work?'},
    retrievalConfiguration={
        'vectorSearchConfiguration': {
            'numberOfResults': 20
        }
    },
    knowledgeBaseId=kb_id,
    modelId='anthropic.claude-sonnet-4-6'  # Pin after benchmark — Sonnet 5 (2026-06-30) for agentic lanes; verify in console
)
Caching for repeated queries:
If you ask the same questions repeatedly, use Bedrock’s prompt caching to avoid re-retrieving and re-embedding:
response = bedrock_runtime_client.invoke_model(
    modelId='anthropic.claude-sonnet-4-6',  # Pin after benchmark — Sonnet 5 (2026-06-30) for agentic lanes; verify in console
    body=json.dumps({
        'system': [
            {
                'type': 'text',
                'text': 'You are a helpful assistant with access to company documentation.'
            },
            {
                'type': 'text',
                'text': context,
                'cache_control': {'type': 'ephemeral'}
            }
        ],
        'max_tokens': 2048,
        'messages': [{'role': 'user', 'content': 'How does our cost optimization framework work?'}]
    })
)
This caches the context for 5 minutes, reducing costs on repeated queries by 90%.
Common Mistakes to Avoid
Uploading unstructured data without preprocessing
- PDFs with images: Bedrock’s native parser may miss image content. Pre-OCR large documents.
- Tables: Convert to markdown or JSON for better chunk coherence.
Using too many documents
- Knowledge bases with 100,000+ documents can hit retrieval latency. Consider partitioning into multiple KBs by domain.
Not setting metadata
- Without metadata, every query retrieves from the entire KB. Add department, product, or date metadata to narrow results.
Ignoring the $108/month minimum
- The knowledge base collection runs 24/7. If you don’t query it frequently, disable it or delete it.
Next Steps
- Ingest your first batch of documents
- Test retrieval with sample queries
- Monitor costs in the AWS Bedrock console
- Deploy to production with error handling and monitoring (e.g., CloudWatch alarms for failed retrievals)
- Talk to FactualMinds if you need help scaling to production volume or custom embedding models
For multi-tenant Bedrock isolation patterns, read multi-tenant GenAI on Bedrock.
Related reading
- Bedrock Provisioned Throughput vs On-Demand: Break-Even Math
- How to Set Up Amazon Q for Business with SharePoint and S3
Frequently asked questions
What is the difference between Amazon Bedrock Knowledge Bases and a manual RAG pipeline?
Manual RAG requires you to manage the chunking strategy, embedding model selection, vector database, and context injection yourself — usually with Langchain or similar libraries. Amazon Bedrock Knowledge Bases automates this: you upload documents, Bedrock chunks and embeds them (using its own models or custom embeddings), stores them in its own managed vector database, and retrieves context on-demand. The trade-off: you lose flexibility in embedding models and chunking strategies but gain operational simplicity. For production use, Knowledge Bases is ideal if you accept its default settings; manual RAG is necessary if you need fine-grained control over embedding models, chunk sizes, or custom retrieval logic.
How much does Amazon Bedrock Knowledge Bases cost per month?
Bedrock Knowledge Bases pricing is $0.15 per hour that the knowledge base is provisioned (always-on cost = $108/month minimum), plus $0.15 per 1,000 PUT requests (ingestion), $0.15 per 1,000 GET requests (retrieval), and $0.08 per 1M tokens for on-demand embedding generation (if using Bedrock embeddings). A knowledge base with 10,000 documents ingested in bulk, then queried 100 times per day = ~$108/month baseline + $0.45/month ingestion + $4.50/month retrieval + embedding costs. This is competitive with self-managed OpenSearch Serverless for small to medium scale; at 10,000+ queries/day, self-managed becomes cheaper.
What is the maximum size of a single document that Knowledge Bases can ingest?
Amazon Bedrock Knowledge Bases supports documents up to 50MB per file, with a total knowledge base size limit of 10GB per knowledge base instance. For larger document sets or multi-tenant scenarios, partition documents into multiple knowledge bases or use retrieval strategies like filtered metadata queries. The 50MB limit applies to individual files (PDFs, Word docs, etc.), not the content after chunking — Bedrock chunks documents into 2KB overlapping segments by default.
Can I use custom embedding models with Amazon Bedrock Knowledge Bases?
Yes. Amazon Bedrock Knowledge Bases integrates with Amazon Titan Embeddings (the default), but you can also bring your own embeddings if you host an embedding endpoint (e.g., SageMaker hosting Hugging Face model endpoints). Configure "External Vector Store" mode: Bedrock chunks documents and calls your external embedding API, then stores vectors in your OpenSearch Serverless or self-managed vector database. This adds operational overhead but allows models like Cohere Embed, MistralAI embeddings, or proprietary models trained on your domain data.
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.