94,000 Trials Later, the Same Models Cost About 2× Under a Different Harness
Quick summary: On October 13, 2026 the Strands Agents team published about 94,000 Harbor trials. On matched Anthropic runs, estimated cost ran from about $0.74 to $1.57 per trial.
Key Takeaways
- On October 13, 2026 the Strands Agents team published about 94,000 Harbor trials
- On matched Anthropic runs, estimated cost ran from about $0.74 to $1.57 per trial
- On October 13, 2026, the Strands Agents team published the follow-up to their September 21 harness release: about 94,000 Harbor trials that hold the model and the task still and change the harness
- The snapshot inside the post is September 17, 2026
- On September 21 they had reported 28% lower token cost than other harnesses on the same Claude and GPT models
Table of Contents
On October 13, 2026, the Strands Agents team published the follow-up to their September 21 harness release: about 94,000 Harbor trials that hold the model and the task still and change the harness. Albert Zhao, Fabio Nonato de Paula, Ariel Nabavian, Owen Kaplan, Morgan Willis, and Chris Smith signed it. The snapshot inside the post is September 17, 2026. On September 21 they had reported 28% lower token cost than other harnesses on the same Claude and GPT models. This pass puts that reduction closer to 34% for Strands harness, which they describe as a general-purpose harness you can tune per task.
The card at the top of this page is their October 13 featured image. The card below is the September 21 featured image, the one that still says 28%. What you install, and where a commerce agent stays on AgentCore, is the September 24 post. This page is how to read the trial chart.
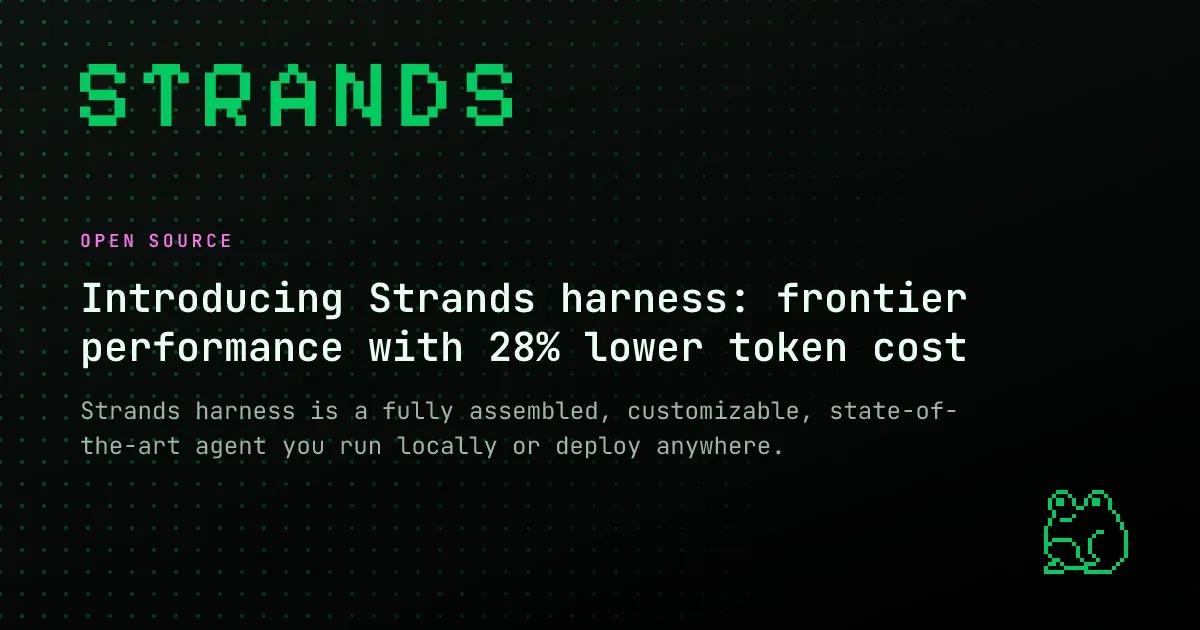
Featured image from Introducing Strands harness, September 21, 2026. The image is theirs. The 28% line on the card is the claim the October 13 study revises.
Cited published figures (not a FactualMinds run) — Strands Agents team, October 13, 2026. Snapshot September 17, 2026. About 94,000 trials on Harbor at high reasoning effort: 8 benchmarks (ALFWorld, ContextBench, GAIA, LoCoMo, SWE-bench Pro, tau-3 bench, Terminal-Bench 2.1, WebShop), 12 models, 6 harnesses (Strands harness, OpenCode, Claude Code, oh-my-pi, Codex, DeepSeek Harness). Dollar amounts are estimates. Token counts were multiplied by a per-model rate taken from trials that reported a billed cost. Strands harness and DeepSeek Harness reported no billed cost. Source: We ran 94,000 trials to measure the cost of harness choice.
A cell counts only if every harness finished it
The full set is about 94,000 trials. The charts use a matched subset: 82,400 trials across 9 models. For each model provider, a harness is scored only on the model-and-dataset pairs every harness in that comparison also finished. Nobody received credit for a combination its rivals skipped.
That rule produced three matched blocks:
- Anthropic: 32 shared combinations, 8,240 trials per harness, five harnesses (Claude Fable 5, Claude Opus 5, Claude Opus 4.8, Claude Sonnet 5).
- OpenAI: 24 combinations, 6,180 trials per harness, four harnesses.
- Open-weight: 16 combinations, 4,120 trials per harness, four harnesses.
Chart accuracy is the mean of those combination-level scores, with errored trials left out. Estimated cost per trial is total estimated cost divided by total trials in the matched subset.
They also left out a model whose full run was still going when the snapshot was taken, a small number of 0.0 scores that reported no error, and a model wave scheduled to run last. The open-weight chart drops Kimi 2.5 because every oh-my-pi run on that model failed, so no combination existed that all four harnesses completed. Most errors in the dataset were agent timeouts and non-zero exit codes. Safety refusals were a smaller share.
Three published cost spans
These rows are their summary figures, dated September 17, 2026. Attribution stays with the Strands Agents team.
| Family | Trials per harness | Estimated cost per trial | Accuracy spread |
|---|---|---|---|
| Anthropic, 5 harnesses | 8,240 | About $0.74 to $1.57 (about 2.1x). Claude Code near $1.57 | 2.75 points |
| OpenAI, 4 harnesses | 6,180 | Strands about $0.20 at 71.02%. OMP about $0.49 at 69.73%. OpenCode about $0.26 at 66.18% | 4.84 points, cost span about 2.4x |
| Open-weight, 4 harnesses | 4,120 | DeepSeek about $0.62. Strands about $1.23 at 41.82%. OpenCode about $1.96 at 42.93% | 5.00 points, cost span about 3.1x |
On Anthropic, estimated cost per trial runs from about $0.74 to about $1.57 for the same models on the same work. Claude Code, near $1.57, lands slightly below the cheapest harness on accuracy. The gap is $0.83 per trial. Across 1,000 tasks that is about $830, which is the scale line in their Anthropic section. On this family the dearest harness was slightly less accurate than the cheapest.
On OpenAI, Strands harness has both the lowest estimated cost, about $0.20 per trial, and the highest accuracy, 71.02%. OMP, about $0.49, scores 69.73%. Strands costs about 59% less than OMP and scores 1.29 points higher. OpenCode uses slightly fewer tokens than Strands, costs about $0.26, and posts the lowest accuracy in that set, 66.18%. Token count and estimated dollars split on that row. They publish both for that reason.
On open-weight models the expensive harness took the accuracy column. OpenCode at about $1.96 scores 42.93%. DeepSeek Harness, about $0.62, is the cheap end. Against Strands harness at about $1.23 and 41.82%, OpenCode costs about 59% more per trial for 1.11 points. Score that gap on tasks you run before you pay it.
An overall average ranked the narrow run first
What broke — Average each harness across every benchmark it happened to run, and Claude Code comes out first. In this evaluation Claude Code ran only on Anthropic models. Codex ran only on OpenAI models. Strands harness, OpenCode, and OMP ran all three families, including open-weight tasks where accuracy falls into the single digits. A blended rank credits a harness for the model families it never entered. The matched, per-provider charts are the comparison that holds the model still.
Billed cost was missing for several harnesses. Strands harness and DeepSeek Harness had no reported billed costs. Others reported a bill for only part of their trials. The gaps were filled from token counts and a per-model rate taken from trials that did report a bill. The $0.74, the $0.20, and the $830 are estimates tied to September 17, 2026.
They credit Strands harness defaults for a share of the gap, especially tool offloading. Bulky tool results go to a JSON file. Later turns send the reference. The September 21 context defaults, and the line between this library and AgentCore Harness, are already in the September 24 post.
Opinionated take: On the Claude and GPT rows in this snapshot, take the cheaper harness when the accuracy gap stays inside a couple of points. Anthropic moved 2.75 points across a 2.1x cost range, and the harness near $1.57 was slightly less accurate than the one near $0.74. On open-weight models, pay OpenCode’s extra 59% when you can score that 1.11 points on tasks you run. Trade-off: you may leave about a point of bench accuracy on the open-weight set. A commerce agent that can change an order, a price, or a payment stays on AgentCore Harness or Runtime. This chart measures loop tokens on public benches.
What to do this week
- If a slide still says “28% lower token cost,” date it September 21, 2026, and put the October 13 reading next to it: closer to 34% on their later pass, as a harness-versus-harness token figure. Link their 94,000-trial post.
- Ask for the match before you quote a rank. Same models, same tasks, which harnesses finished every cell, and whether the dollars are billed or estimated from tokens.
- Put the accuracy gap beside the cost multiple before anyone switches. A 1.11 point gain at about 59% more estimated cost is a workload call. A 2.1x cost gap with the expensive harness slightly less accurate is a harness call.
- Leave order, inventory, and payment workflows on AgentCore. The ship map is that decision. Re-price platform spend on the AgentCore calculator and the 12-component breakdown. The $830 per 1,000 tasks is their Anthropic bench gap. It is a different meter from the platform figure in the September 24 post.
- Write September 17, 2026 next to any number you paste into a review deck. They already name Opus 5.5, GPT-6.1 Sol, and Muse Wonder as models that can move these points after the snapshot.
What this post doesn’t cover
We did not re-run Harbor, and this page publishes no FactualMinds token-cost number for these 94,000 trials. The dataset, the exclusions, and the scatter charts belong to the Strands Agents team. The table above repeats their published summary figures so you can compare families on one page. Their plots stay on their URL.
Context-window defaults, the September 21 Terminal-Bench comparison, and the boundary between Strands harness and AgentCore Harness stay in the September 24 post. Evals for a live order-status task are a different job from a Harbor mean: start with the evals harness note if that is the decision in front of you.
FactualMinds has no published production-agent engagement to attach these numbers to. The standing proof on this site is the 64-part field guide and the calculators linked above.
Frequently asked questions
When should we not treat the 34% or the $0.74 as our AWS bill?
What could go wrong if we rank harnesses by one overall accuracy number?
When is OpenCode's higher open-weight cost worth paying?
What could go wrong after they dropped Kimi 2.5 from the open-weight chart?
Do these figures still hold for Opus 5.5, GPT-6.1 Sol, or Muse Wonder?
Should a commerce agent switch harnesses because Strands was cheapest on Claude and GPT?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.